Deep Dive: Hugo – What a Static Site Generator Does, What Replaced My WordPress Plugins, and How Search Works Without a Server
What Hugo is and how it differs from WordPress, what took over the jobs of Yoast, Polylang and the cache plugins, how a search box works on a site without a server, how I add a post and update Hugo – and which pitfalls only showed up in operation.
🌐 Also available in: Deutsch · Français · Español · Italiano · Português · Nederlands · Polski
Deep Dive in the series around the Ansible Tour. The tour explains the roles, the deep dives the technology underneath: how it works, why it is used this way here, and what went wrong along the way.
In early November this blog moved from WordPress on Kubernetes to Hugo. The experiment with real numbers and the move itself are told elsewhere. This post is the overview I would have liked before starting: what Hugo actually is, what took over the jobs of the WordPress plugins, how a search box works on a site that has no server-side code at all, what I do when I add a post or update Hugo, and where it surprised me.
Table of Contents
🧭 What Hugo is
A printing press instead of a kitchen
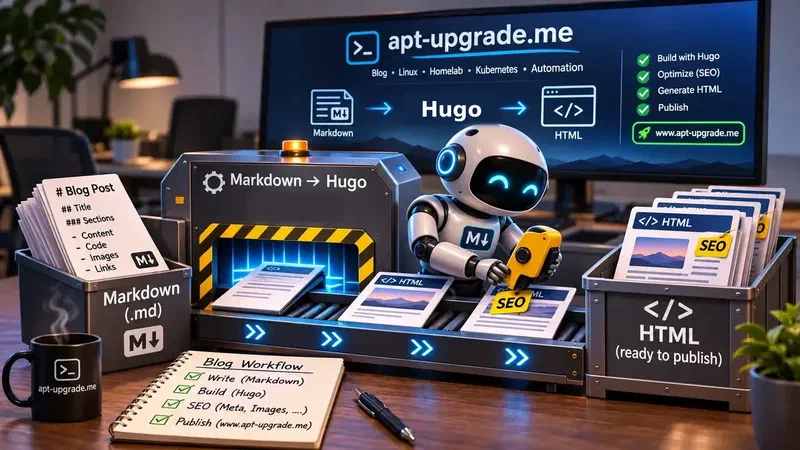
WordPress works like a restaurant kitchen: every time a guest orders, PHP cooks the page from the database – unless a cache plugin has a plate ready. Hugo works like a printing press: it prints every page once, in advance, and the web server only hands out finished copies. Nothing is cooked when a reader arrives.
Technically, Hugo is a static site generator: a single program written in Go that reads Markdown files, templates and images and writes a folder full of HTML, CSS, images and feeds. That folder is the website. Any web server can deliver it; here it is plain nginx.
One binary, two editions
Hugo is one executable with no dependencies – no PHP, no database, no Node.js. It comes in a standard and an extended edition; the extended one adds WebP encoding and Sass. This blog uses the extended edition, version 0.169.0, because every image is resized and converted to WebP during the build.
The takeaway: Hugo moves all the work from the moment of the visit to the moment of publishing. Everything else in this post follows from that.
⚖️ Hugo versus WordPress
| Question | WordPress | Hugo |
|---|---|---|
| When is a page made? | On every request (or from a cache) | Once, at build time |
| What runs on the server? | PHP, MariaDB, often Redis | Only the web server |
| Attack surface | Login, admin, plugins, XML-RPC, PHP | Static files |
| Regular updates | Core, plugins, themes, PHP | nginx; Hugo only on the build machine |
| Where do I write? | Editor in the browser | Text editor, Git |
| Comments, forms | Built in | Need an external service |
| Speed | Cached: 58 ms for the front page | 57 ms – no difference |
| Page weight (front page, no images) | 25 files, 198 KB | 3 files, 9.5 KB |
The numbers come from my own measurements before the move. Speed was not the reason: a well-cached WordPress is just as fast. The reasons were the rest of the table – no login to attack, no plugin updates every week, no database to back up, and a page that is 95 % smaller.
What I gave up: the editor in the browser, comments and the comfort of installing a feature with one click.
The takeaway: WordPress is a program that produces a website. Hugo produces the website once and steps aside. Whether that is better depends on whether you need what only the running program can do.
🔧 How Hugo works
Content: Markdown with front matter
Every post is a Markdown file. At the top sits the front matter, a block of YAML that Hugo reads as data. A post on this blog starts like this:
---
title: 'Zabbix in Containers Watches My Home Network'
slug: zabbix-in-containers-watches-my-home-network
date: '2026-11-13T15:40:00+01:00'
translationKey: zabbix-heimnetz-2026-11
description: 'Short summary for search results, at most about 155 characters.'
categories:
- linux
tags:
- zabbix
image: uploads/2026/11/zabbix-watchman.webp
imageAlt: What the picture shows, for screen readers and search engines
---
Below the second --- comes the text. Markdown covers headings, lists, tables and code; where it is not enough, raw HTML is allowed (unsafe = true in the Goldmark settings), which matters for the posts converted from WordPress.
Folders, sections and addresses
site/
├── content/en/posts/   posts in English (one folder per language)
├── content/de/posts/   posts in German, and so on for eight languages
├── layouts/            templates: the theme
├── assets/             CSS and JavaScript, processed by Hugo
├── uploads/            images and downloads
├── i18n/               interface words per language ("Read more", "Search")
├── data/               menus, flags, footer text as JSON
└── hugo.toml           configuration
hugo.toml decides the addresses: posts = "/:year/:month/:day/:slug/" keeps the URL scheme WordPress used, so no old link broke. Categories and tags are taxonomies; Hugo builds a page for every category and every tag by itself.
Templates
The templates use Go’s template language. baseof.html is the frame of every page, page.html a single post, home.html the start page, and partials are reusable pieces – the header, the sidebar, the <head> with all meta tags. I use no ready-made theme: the layouts were written to look like the old WordPress theme.
The asset pipeline
Hugo processes files itself: resources.Get "css/main.css" | minify | fingerprint minifies the stylesheet and puts a hash into its file name, so browsers can cache it forever. Images are resized during the build – the preview image for social media, for example, is created from the post image at 1200 px and made smaller until it stays under 280 KB, the limit for WhatsApp previews.
Multilingual from the start
Each language has its own content folder, label and locale in hugo.toml. Posts that belong together share a translationKey; from that Hugo knows the translations of every page and builds the language switch and the hreflang links. This blog has eight languages now – English, German, French, Spanish, Italian, Portuguese, Dutch and Polish.
Preview and drafts
hugo server builds the site into memory and serves it on localhost:1313; every saved file reloads the browser. draft: true keeps a post out of the real build, and so does a date in the future – more on that one below.
The takeaway: content, templates and configuration are three separate kinds of files. You can change the look without touching a single post, and write a post without knowing how the templates work.
🧩 Where the plugins went
On WordPress, almost every feature was a plugin. On Hugo, a feature is either built in, a few lines of template, or a small script that runs after the build.
| WordPress plugin | Job | Now |
|---|---|---|
| Yoast SEO | Title, description, canonical, Open Graph, structured data | head.html (one template for all pages) |
| Yoast SEO | Sitemap | Built into Hugo, own sitemap.xml template with hreflang |
| Yoast SEO | “Your post has no description” | check_posts.py: the build stops |
| Polylang | Languages, language switch | Built into Hugo |
| CompressX | WebP images, smaller sizes | Hugo image processing |
| Autoptimize | Minify CSS, JS, HTML | hugo --minify |
| WP Super Cache, Redis | Page and object cache | Not needed – every page is already a file |
| Search (WordPress) | Full-text search | Pagefind (next section) |
SEO without a plugin
Yoast did three things: it wrote meta tags, it built a sitemap, and it nagged. The first two are now one partial, head.html. For every page it writes the title (or a shorter seoTitle from the front matter), the description, a canonical link, one hreflang link per translation, the Open Graph and Twitter tags with a generated preview image, the article dates, and a JSON-LD block with the same structured data Yoast produced (Article, WebPage, BreadcrumbList, Person). It is one file, and it is the same for every page – no settings screen per post.
The nagging moved into the build: tools/check_posts.py stops the build if a post lacks a title, description, image, image text, translation key or date, or if the image file does not exist, and it warns when a description gets too long or a translation is missing.
Extensions in Hugo
Hugo has no plugin store, but it has extension points:
- Themes and Hugo Modules – complete looks or pieces of one, pulled in like a dependency. This blog mounts its own folders through
module.mounts(the upload folder is mounted twice: once for image processing, once as/wp-content/uploads/so the old image addresses keep working). - Shortcodes – small templates you call from Markdown, e.g. for a video or a notice box.
- Render hooks – your own template for every link, image or heading Markdown produces.
- Output formats – the same content as HTML, RSS, JSON or anything else.
- Tools after the build – the build is just a folder, so any program can work on it. Here,
imgattrs.pyaddssrcsetand lazy loading to the images inside old posts, and Pagefind builds the search index.
The takeaway: most plugins solved problems a static site does not have. The rest became a template or a script that I can read in full – which also means nobody else updates them for me.
🔍 How search works without a server
A search box seems to need a server: someone has to look up the words. Pagefind moves that work, too, into the build.
- At build time, Pagefind reads every finished HTML page. It only indexes the part marked with
data-pagefind-body(the article), so menus and sidebars do not pollute the results, and it skips anything markeddata-pagefind-ignore. It detects the language from thelangattribute and builds one index per language. - The index is split into many small files under
/pagefind/– 18 MB in total for eight languages. Nobody downloads all of it. - In the browser, nothing is loaded until someone actually searches. Then a few lines of JavaScript import Pagefind, which fetches only the index pieces for the words typed and the fragments of the matching pages, and shows title and excerpt.
import('/pagefind/pagefind.js')
  .then(function (m) { return m.search(term); })
  .then(function (r) { return Promise.all(r.results.slice(0, 8).map(function (x) { return x.data(); })); })
A side effect I like: the search term never reaches the server as a query string, so it does not end up in an access log. The form is hidden for browsers without JavaScript on purpose – a plain form submission would have put the term into the URL.
The takeaway: “static” does not mean “no interaction”. It means the interaction happens in the reader’s browser with data that was prepared in advance.
✍️ My workflow for a new post
- Write the Markdown file in
site/content/en/posts/<slug>.mdwith the front matter above. The translations get the same file name, the sametranslationKey, and tags with a language suffix (hugo-de,hugo-fr, …). - Add the image to
site/uploads/YYYY/MM/– WebP, at most 1536 px wide, under 280 KB. Inside the text, images are referenced as/wp-content/uploads/YYYY/MM/name.webp, the address WordPress used. - Build:
tools/build.sh
It runs check_posts.py, then hugo --gc --minify, then imgattrs.py, then Pagefind. Hugo itself needs about ten seconds for the whole site.
- Publish:
tools/deploy.sh <host> 10022
rsync uploads the build into an incoming/ folder; the server then copies it into a new release folder and switches a symlink to it in one step. The last five releases stay, so tools/deploy.sh <host> 10022 rollback goes back in a second. The deploy key can do nothing else – the server only accepts exactly these commands for it.
- Commit and push the content repository.
Two repositories: open code, private content
The server and the build tools live in a public repository, www_hugo, next to the Ansible code for everything else. The content – posts, images, templates, drafts – lives in a private one. The reason is that a repository remembers everything: an image I take offline would stay in the history of a public repo forever, and drafts are not meant for readers. The server only receives finished files through the deploy step; it never sees a draft, and the public repo never sees the content at all.
The takeaway: publishing is two independent steps. The server shows what was last deployed, Git keeps what was last committed – I do both, in that order.
⬆️ Updating Hugo
Hugo is not installed on the server at all. It lives as a single binary in .tools/ on the machine that builds the site, together with Pagefind. The versions are pinned in versions.yml of the public repo:
hugo_version:                "0.169.0"   # github.com/gohugoio/hugo/releases
pagefind_version:            "1.6.0"     # github.com/Pagefind/pagefind/releases
An update follows the same pattern as everywhere else here:
- Read the release notes – Hugo deprecates template functions now and then and warns about them in the build output long before it removes them.
- Download the extended release for Linux, compare its SHA-256 with the checksums file of the release, replace
.tools/hugo. - Build into a separate folder and compare it with the previous build (
diff -r). Only expected differences should show up. - Change the pin in
versions.yml, deploy, commit.
Because the server only serves files, a Hugo update can never break the running site. The worst case is a build that fails or looks different – and that happens on my machine, not in front of readers.
The takeaway: the generator is a build tool, like a compiler. Pin it, update it on purpose, and compare the output.
🤖 What Claude does around Hugo
Most of the work on this blog is done together with Claude (Anthropic’s AI) in the terminal. Broken down by topic:
- Migration: export from WordPress, conversion of every post to Markdown with front matter, old addresses and image paths kept, redirects for changed slugs.
- Templates and look: rebuilding the old theme in Hugo templates, the slider, the sidebar, the dark corners like the date archive pages.
- SEO: the
head.htmlpartial, the sitemap withhreflang, structured data, preview images under the WhatsApp limit. - Writing and translating: drafts in my words, translations into all eight languages with fixed rules (code blocks byte-identical, links rewritten per language) and a checker that compares every translation with the English original.
- Checks: the build check, a link check over all generated pages, a live check against the running site.
- Server and deploy: the Ansible role for nginx, the atomic deploy, SELinux, monitoring.
- Troubleshooting: finding out why a post did not appear (see the next section) or why a breadcrumb pointed to a missing page.
What stays with me: deciding what is written and published, reading every draft, running the playbooks, and every push and deploy – Claude asks before each one.
The takeaway: a static site is text files and small scripts – exactly the material an AI assistant handles well. The decisions are still mine.
🐛 Pitfalls that only showed up in operation
- A post from the future is not built. I set a post’s date to 15:50 and built at 15:44 – Hugo silently left it out. No error, the post was just missing.
datemust be in the past, or the build needs--buildFuture. - A missing day page. The breadcrumb of a new post linked to its day archive (
/2026/11/13/), which did not exist because the date pages are content files, not generated ones. The link check found it; now a new date needs its_index.md. And while writing this very post, both mistakes happened again: the post was dated 08:30 and built at 08:22, and its new day page carried 12:00 – a page dated at noon is in the future all morning. - Converted HTML is fragile. Posts imported from WordPress are a mix of Markdown and raw HTML. In a few of them, words were glued together or a stray
**survived. Only a check of the rendered pages across all languages found them. - Typography settings matter. Hugo’s typographer turns
--into a dash by default. WordPress did not, so commands like--checkwould have turned into–checkin old posts. The setting now only touches quotes and apostrophes. - Not everything belongs in search and feeds. The imprint and privacy policy contain the postal address. They are
noindex, kept out of the RSS feeds and out of the Pagefind index – a plugin would have needed a setting for each of those, here it is a condition in the templates. - Some addresses come from front matter. A few old posts carry a
url:key with the full path. In translations it needs the language prefix, otherwise all languages claim the same address.
The takeaway: Hugo does exactly what it is told and rarely complains. The checks that WordPress plugins used to do quietly have to be written down – and then they run on every build.
📊 Measured
| Posts | 146, in 8 languages |
| Generated HTML pages | about 23,000 (posts, tags, categories, archives) |
| Hugo build | about 10 s (whole site) |
| Output folder | 498 MB, nearly all of it images |
| Search index | 18 MB for 8 languages, loaded in small pieces |
| Software on the server for the blog | nginx |
🎯 The lessons
- Decide where the work happens: at the visit (WordPress) or at publishing (Hugo).
- Check what a plugin really did before replacing it – most of it is one template, some of it is a check you have to write yourself.
- Search, feeds and sitemaps work without a server when the build prepares the data.
- Pin the generator like any other build tool and compare the output before deploying.
- A missing post with no error message is usually a date in the future.
- Keep content and code apart when the code is public.