Bare Metal to K3s: A Nextcloud Migration Battle Log
🌐 Also available in: Deutsch · Français · Español
Today I moved a production Nextcloud from a cozy native bare-metal install to a shiny K3s/container stack. On paper: pull a backup, restore it, flip DNS, done. In practice: a series of small landmines, each invisible until you step on it. Here’s the battle log. 🪖
Table of Contents
Step 1: shovel the data 🚚
The heavy lifting was an rsync of ~360 GB of user data plus a ~330 MB SQL dump from the backup box into the new node. Because I pre-synced earlier in the day, the final run only shipped the delta — the whole thing came down to a fast incremental copy. Lesson old as time: pre-seed, then the cutover sync is tiny.
Step 2: the Major Version Gauntlet 🎮
The backup was Nextcloud 32.x. The target stack runs 34.x. Nextcloud has one hard rule: you cannot skip a major version. So it’s a walk, one step at a time:
32.0.14 → 33.0.9 → 34.0.4 (occ upgrade at every step)
The container twist: the code lives in a persistent volume, and Nextcloud refuses to run older code against a newer data version (“downgrade not supported”). Restoring a v32 database onto a pod that still had v34 code = instant refusal. The fix is delightfully hacky: pin the image to the matching version, nudge the code volume’s version.php so the entrypoint re-lays the correct code, and let each occ upgrade finish (its readiness probe blocks until the DB migration is done — patience required).
The invisible landmines 💣
1. The antivirus socket of doom
After the restore, the Files app threw a bare “Internal Server Error” right after login — and the log stayed empty, because the crash happened below Nextcloud’s own logger. Cause: the restored config re-enabled files_antivirus in socket mode, pointing at a ClamAV daemon socket that exists on the old native box but not in the container. Fix: disable the app (this stack does nightly batch scans instead). Diagnosed only by noticing, not by any log line. Sneaky.
2. Let’s Encrypt jail 🔒
DNS wasn’t pointed at the new box yet, so cert-manager had spent days failing to issue certificates. When I finally flipped DNS, the certs still wouldn’t issue. Why? After enough failures, cert-manager parks the Certificate in an exponential back-off stored in the object’s status — next attempt scheduled ~24 hours out. Restarting the controller? Ignored. Deleting the secret? Ignored. The move that actually works: delete the Certificate object and let the ingress-shim recreate it fresh, with no failure history → instant issuance.
Bonus trap: Let’s Encrypt’s HTTP-01 check prefers IPv6. If you only move the A record and forget the AAAA, validation keeps hitting the old host and failing while everything “looks” switched. Move both. Always both.
The main event: the checkbox that lied ☑️
This one cost the most head-scratching. Collabora (Nextcloud Office) refused to open documents: “Nextcloud Office could not be loaded.” Meanwhile the admin panel’s Office connectivity test was reassuringly green: “Collabora Online server is reachable.” Server-side everything checked out — discovery 200, capabilities 200, valid certs, correct WOPI URL, WebSocket headers present, identical to a known-good reference host.
The difference turned out to be a single setting carried over from the old server: “Disable certificate verification (insecure)” was ticked (disable_certificate_verification=yes in richdocuments). On the old box it made sense — self-signed certs. But now, with valid Let’s Encrypt certificates, that “insecure” mode breaks the WOPI document session in richdocuments 11.x — while leaving the admin connectivity test perfectly green, because that test uses a different code path than the actual document handshake.
Why do I think it was the culprit? Because the fix was exactly that: untick the box (delete the key), retry, and documents opened immediately. My theory: the insecure/no-verify path and the WOPI token exchange disagree once real TLS is in play, and the failure surfaces only in the editor session — the classic “the health check is green but the feature is dead” situation that keeps sysadmins humble. Two more prod-leftover keys (public_wopi_url, doc_format) went out with it, matching the reference host’s minimal config.
The red herring: “why are so many apps disabled?” 🎣
Post-upgrade, a pile of apps showed as disabled (dashboard, comments, external storage, …) and I braced for a reconcile marathon. Then I diffed the current app set against the old server’s state (extracted from the pre-upgrade DB dump). Plot twist: they were disabled on the old box too. The new instance already matched production. The only genuine casualty was metadata, which simply has no version compatible with Nextcloud 34. Sometimes the scary diff is just… the truth.
Native vs. containers: the honest bit ⚖️
The new instance feels a touch slower than the old native one. RAM and CPU sit bored (plenty of headroom), and server-side response times are 50–210 ms — perfectly healthy. The difference is architectural: containers add hops (ingress proxy, overlay network, PHP-FPM↔nginx over the pod network, DB across the pod/host boundary). Per request it’s milliseconds; across the many requests a Nextcloud page fires, it adds up to “slightly less snappy.” That’s the tax you pay for reproducibility, isolation and painless upgrades — and for a small org it’s a trade worth making.
The great database cleanup 🗃️
Restoring a database from an old server drags its entire history along. The file-cache index was carrying the old server’s file paths under superseded storage IDs — plus a long-removed OnlyOffice bundle whose 276k index rows outlived the app. Net result: a oc_filecache table with 1,053,373 rows, of which ~93% were dead weight, and a 1 GB database.
The cleanup, done carefully with a backup and control values (real user files and user count must not change): drop the 7 orphaned OnlyOffice tables, delete the two stale storages (the old native path and an earlier container mapping) after verifying they held zero real files — only regenerable app-data — then OPTIMIZE to hand the freed pages back to the filesystem. Outcome:
oc_filecache rows:  1,053,373  →  72,580
database size:          1 GB   →  282 MB   (-72%)
real user files:       56,183  →  56,183   (unchanged ✔)
users:                    151  →  151      (unchanged ✔)
And on disk: 27 GB of orphaned preview thumbnails whose index had just been deleted. Previews are a pure, regenerable cache — deleting the orphaned tree reclaims the space and Nextcloud rebuilds thumbnails on demand. (The lesson from an earlier rehearsal: never re-index orphaned previews — that just shovels ~500k dead rows back into the table you just cleaned. Delete them instead.)
Bonus gremlin: the empty network graphs 📉
node_exporter was happily reporting CPU, RAM and disk to Grafana — but every Network Traffic panel was stubbornly blank. The metric node_network_receive_bytes_total simply wasn’t there. The clue was in node_scrape_collector_success{collector="netdev"} 0 and the log line:
netdev: "couldn't get netstats: socket: address family not supported by protocol"
Modern node_exporter reads NIC stats over a netlink socket — and the service’s systemd hardening had RestrictAddressFamilies=AF_INET AF_INET6, which quietly forbids AF_NETLINK. The collector fails silently, the metric never appears, the graph stays empty. Add AF_NETLINK to the allow-list, reload, restart — and the traffic curves spring to life. (Bonus déjà vu: the exact same AF_NETLINK omission had bitten MariaDB’s hardening earlier in this project. Sandboxing giveth security and taketh away netlink.)
Watching the machine think 📊
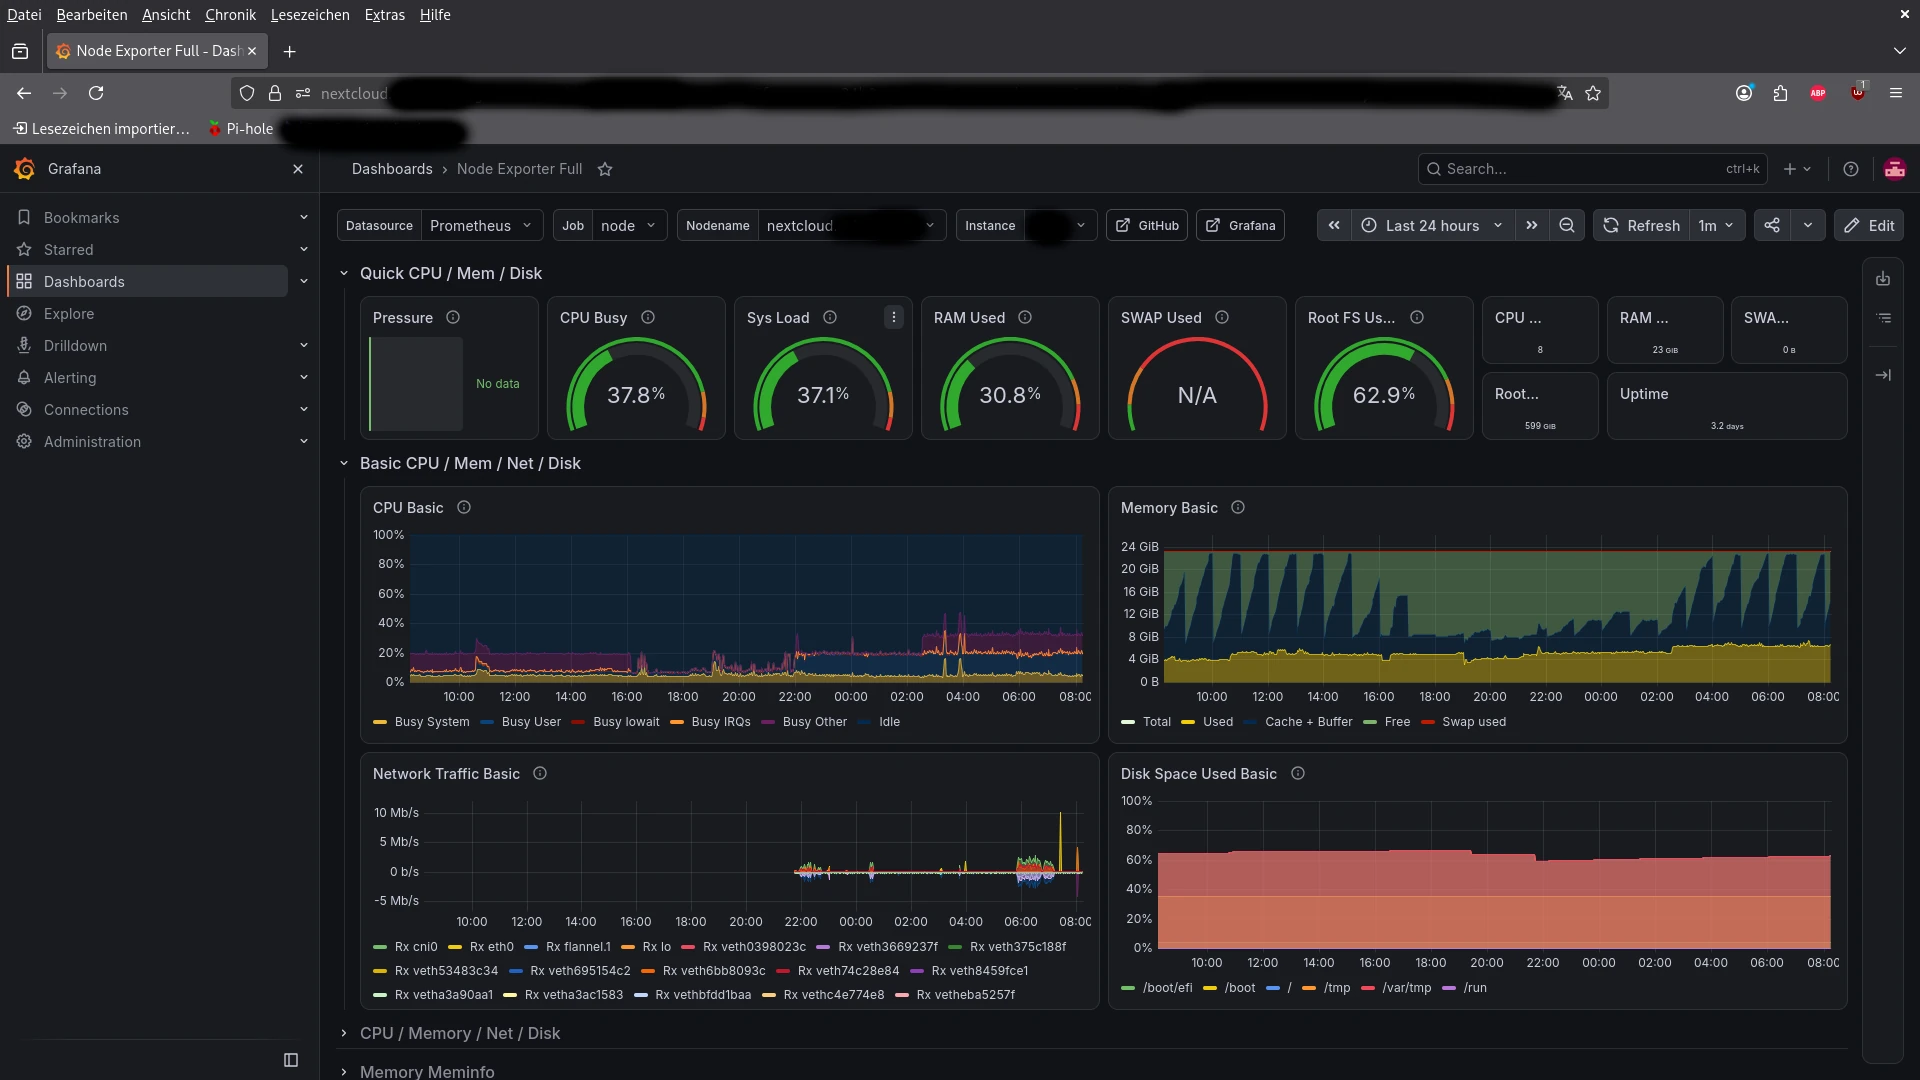
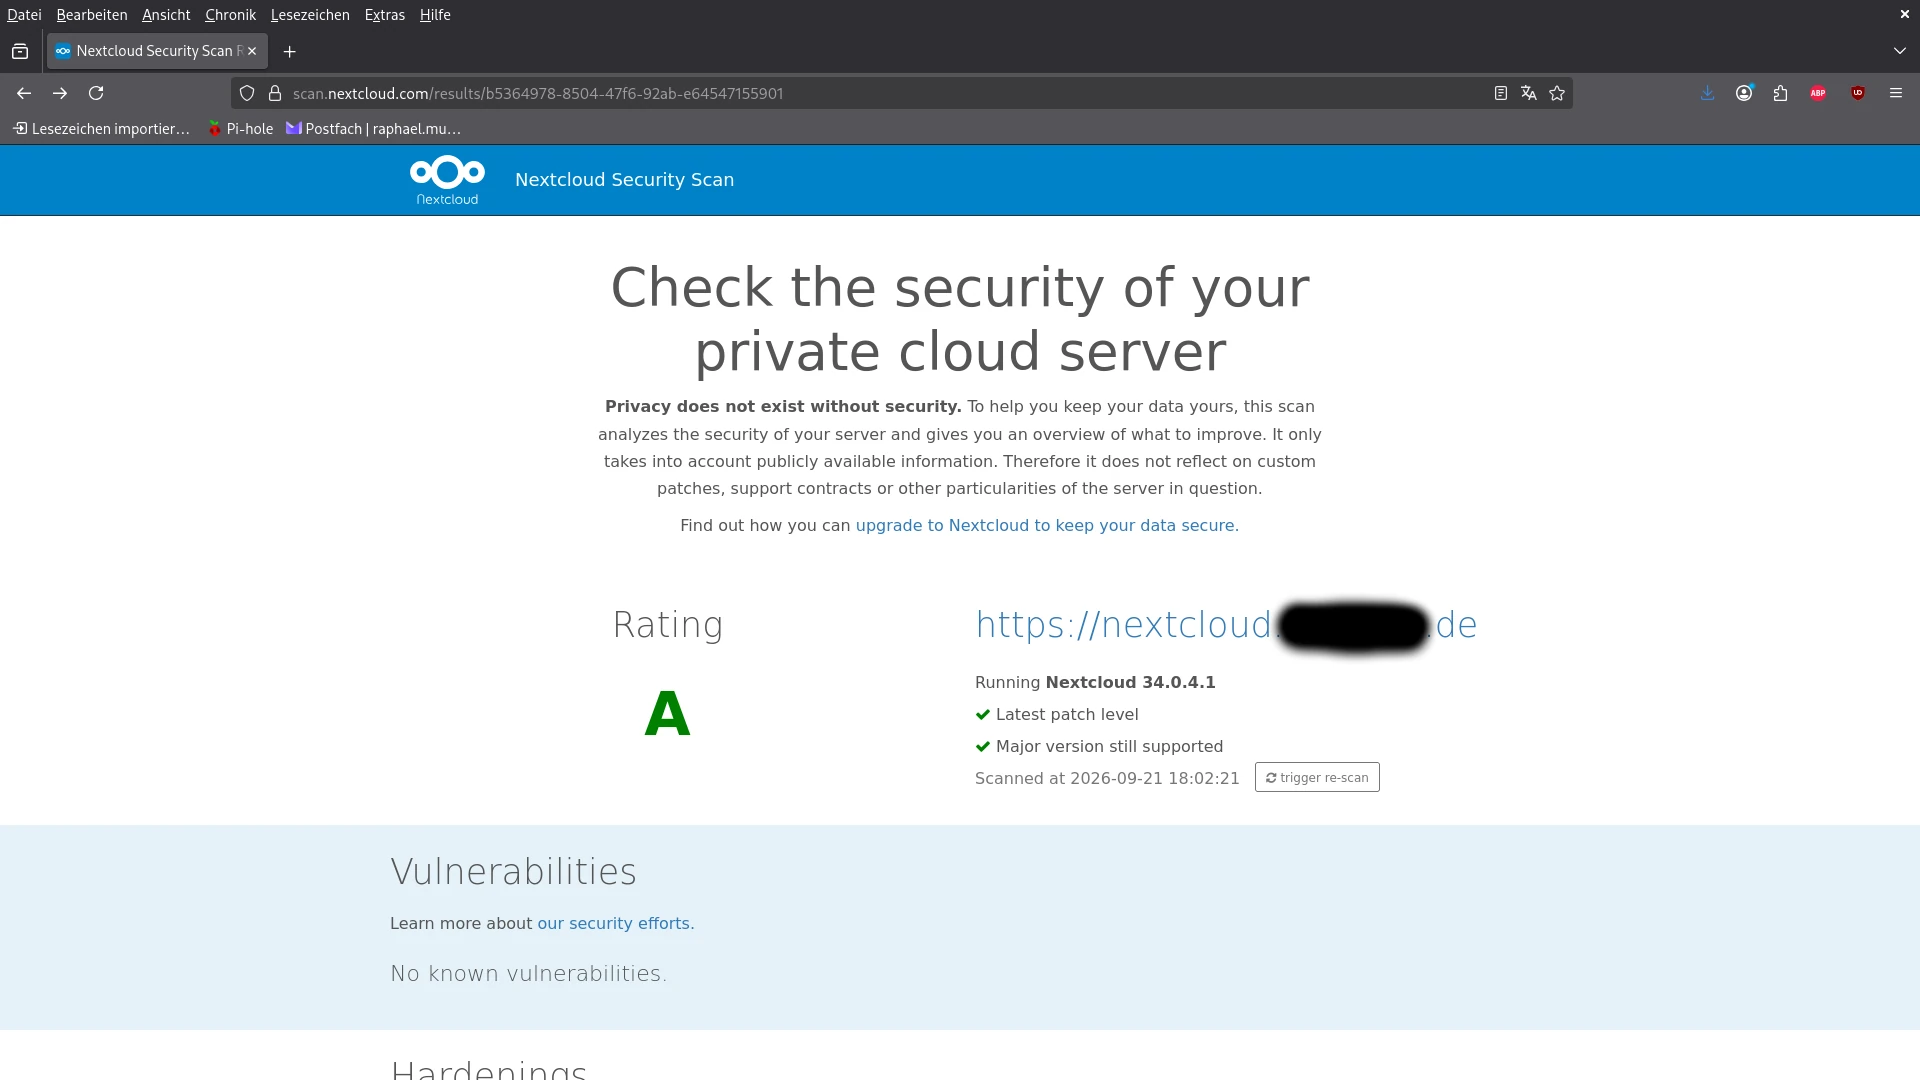
Two related housekeeping moves rounded things off. First I deleted the 27 GB of orphaned preview thumbnails (their index was already gone from the DB cleanup above) — previews are a pure cache, so no harm done. Then, rather than let every early tester pay the on-demand “generate this thumbnail while you wait” tax, I kicked off a full regeneration with occ preview:generate-all. That job has been grinding away the entire night, chewing through ~35,000 images, PDFs and videos — the dashboard above is it caught in the act, and the scanner below is that same run rebuilding previews file by file.
Which leads to a small confession: I never had a dashboard like this before. Seeing CPU, load, memory and — now that the netlink gremlin is fixed — network throughput in real time is weirdly satisfying. I’m genuinely curious what it’ll look like in everyday use: will I get nice clean spikes when someone mass-uploads a whole photo shoot, or a team pulls down an entire gallery? I don’t know yet — and that’s half the fun. Ask me again in a week, once I’ve stared at these graphs long enough to have opinions about percentiles I didn’t know I had. 😄
Afterword: probes that actually restart a wedged pod 🩺
A day in, I went back and fixed something that had been nagging me. The pods had readiness probes — Kubernetes knew when not to send traffic — but their liveness check was the toothless kill -0 1, which only notices once PID 1 has already died (by which point the container is gone anyway). A process that’s still running but wedged — FPM stuck, no longer accepting on its socket — would just sit there, broken, until a human noticed. On a single-replica pod that’s precisely the case you want handled automatically.
The fix is a proper three-probe setup on each container: a startupProbe that holds both liveness and readiness off until the app truly listens (up to ~10 minutes of grace, so a slow occ upgrade or a preview burst at boot never trips a restart loop), a readinessProbe that gates traffic, and a tight livenessProbe — a real tcpSocket connect, not a PID check — that restarts the container only once it genuinely stops answering. The startup gate is the load-bearing piece: without it, a liveness probe strict enough to catch a wedge would also execute a container that’s merely booting slowly. The blog runs the same stack, so it got the identical treatment for parity.
Afterword: tuning to the metal 🎛️
Once the dust settled, the fun part began: watching the new Grafana dashboards and tuning against what they actually showed rather than what I’d guessed. The box turned out to have far more headroom than I’d assumed — 8 cores, 23 GB of RAM, ~16 GB free at rest — so I stopped being stingy. Collabora went from 4 to 6 pre-forked child processes, and its limits from 3 to 6 GB and 2 to 4 cores, which smooths out the occasional cold-start hiccup the first time someone opens a document after an idle spell. A few other bits of polish landed alongside: read-only root filesystems on the sidecars, a saner log level (fatal-only hides the warnings you actually want), and teaching node_exporter to stop reporting three dozen virtual container interfaces so the network graph shows the one NIC that matters. All of it lives in the same Ansible repo — reproducible, versioned, and boring in the best possible way.
Putting on the black hat 🕵️
Before calling it done, I did what any paranoid admin should: I attacked my own instance from the outside. No port scans — apart from the web ports and a key-only SSH port, the firewall silently drops everything, so there’s little to find — just the requests a real opportunist fires at a fresh Nextcloud, hunting for a soft spot. The short version: there wasn’t one.
Every sensitive path came back a flat 403 — config/, data/, .htaccess, .git/, 3rdparty/, the lot. WebDAV and remote.php demand auth (401) before they say anything. The Server header is a laconic nginx with no version, no X-Powered-By, no PHP fingerprint to line up against a CVE list. TLS is 1.3 with a valid Let’s Encrypt certificate; 1.0 and 1.1 are refused outright. The full security-header set is in place — HSTS with preload, a nonce-based CSP, nosniff, frame and referrer policies, a locked-down permissions policy, and __Host- cookies. Nextcloud’s own code-integrity check reports zero modified files.
The part I care about most: brute-force throttling is on, and — because the reverse-proxy chain forwards the real client IP correctly — it throttles the attacker, not my own ingress. That’s the failure mode that quietly neuters rate-limiting on a lot of proxied setups, so it’s worth verifying rather than assuming. None of this is exotic; it’s mostly the boring, correct defaults plus a few deliberate touches. Which is the whole point — the most discouraging thing an attacker can find is a wall with no seams. 🧱
Day three: tying up the loose ends 🧹
The preview marathon from above finally finished at dawn on day three, after well over a day of chewing through the whole library. With nothing writing into the file index anymore, the deferred housekeeping could run — and a proper end-to-end check afterwards turned up two gremlins that had been hiding in plain sight.
The “empty” tables that weren’t
My own notes said the leftover tables of long-gone apps (Talk, Polls, Collectives, Maps) were empty and ready to drop. Before dropping anything I counted rows anyway. They weren’t empty: a couple of dozen wiki pages, a few polls with votes, several dozen chat rooms. Nobody can see them right now, because the apps aren’t installed — but reinstall an app and it picks its old tables right back up. So they stay. What did go: the last on-disk remnants of OnlyOffice (archived first, then deleted), plus a full OPTIMIZE that squeezed the fragmentation from 59 MB down to 2 MB in 17 seconds. Lesson: trust row counts, not your own summary from yesterday.
Push, not poll: notify_push 📡
Nextcloud’s sync clients normally ask the server every ~30 seconds: “anything new?” The notify_push app (Client Push) flips that around — a small Rust daemon keeps a WebSocket open, and the server announces changes the moment they happen. (It has nothing to do with notifications on your phone; those go through Nextcloud’s push proxy and worked all along.) On a native box it’s three pieces: the app, a systemd service, and a location /push/ in the web server. On K3s it’s the same three pieces in different clothes: the app, its own Deployment, and an Ingress route.
I had built the Ansible side the day before, switched off. Reviewing it before flipping the switch found four bugs that would have produced the worst possible outcome — a green playbook run and a dead feature, because every step was set to tolerate failure. occ ran as root (Nextcloud refuses). The binary was picked with a glob — and alphabetically, aarch64 comes before x86_64. The container ran as root with all capabilities dropped, which sounds safe until you realize that root without CAP_DAC_OVERRIDE can’t read a 0640 file owned by www-data — such as config.php. And the ingress passed /push/… through unchanged, while the daemon expects /ws at its root.
Even with all four fixed, the first self-test came back with a 404 — rendered by Nextcloud. The route existed; nginx just never picked it. The Nextcloud routes are a catch-all regex, location ~ "^/", and in nginx a regex beats a plain prefix. So the push route had to become a regex too — and then it still lost, because the ingress controller emits regex locations in alphabetical order of the Ingress name, and nginx takes the first match. notify-push-routes sorts after nextcloud-routes; renamed to nextcloud-push-routes (“p” before “r”), it wins. Not my proudest fix, but a documented one. All six self-tests went green, and the first browser session upgraded to a WebSocket (HTTP 101) and received its first file events. Honest verdict: for a handful of desktop clients it’s a nice-to-have — changes arrive in seconds instead of up to half a minute — not a game changer.
Gremlin #1: the hardening that took down the database
While a playbook run was in flight, Nextcloud briefly answered 500. MariaDB had been stopped — cleanly, no crash. The journal told the story: two seconds earlier, the OS-hardening role had removed the rsync package as “unused on this host”. That was true on the blog host, where it had been verified. On the Nextcloud host, the MariaDB-server package requires rsync — its Galera cluster tooling ships an rsync-based state-transfer script, even on a single node that will never join a cluster. So dnf dutifully removed MariaDB along with it, which stops the service; a later role reinstalled both, and another started the database again. Net effect: two to three minutes of downtime on every single playbook run, invisible unless you happened to be looking at the right moment. The fix is one guard: only remove rsync if rpm -e --test rsync says nothing depends on it. “Verified on host A” is not “true on host B”.
Gremlin #2: the alerts that could never fire
The Grafana alert rules — disk, memory, CPU, node down — looked perfectly fine in the UI. In the log, every one of them failed on every evaluation with condition must not be empty: the provisioning code never told Grafana which query decides the alert. And because the rules treated evaluation errors as “OK”, nothing ever turned red. One missing field, "condition": "B", and they evaluate properly now. An alert that can’t fire looks exactly like a healthy system — the most dangerous kind of green there is. (Basic mail alerting via Monit was in place the whole time, so the box wasn’t flying completely blind.)
Gremlin #3: the port-scan ban that wasn’t
An earlier version of this very post claimed that a port scan “earns you an instant fail2ban timeout”. It didn’t. fail2ban only reacts to log lines, and the firewall logs dropped packets at a deliberately tiny rate, so a scan simply vanished into the default-drop policy. Harmless, but nobody got banned either. The firewall even had a pair of sets labelled “port-scanner blocklist”, and nothing scan-related ever filled them. The fix now lives in the kernel: the last rule before the final drop counts connection attempts per source, and it only ever sees packets headed for closed ports, so normal traffic never counts. A source that keeps knocking gets dropped on every port for a while. No logs, no daemon, no parsing.
Rolling that out surfaced one more trap. The stock nftables service reloads with flush ruleset, and on the Nextcloud host kube-proxy, flannel and Calico keep their rules in nftables too. So every firewall change had also wiped Kubernetes’ own networking, for up to a minute and a half, until it re-synced. Now the ruleset replaces only its own table, in one atomic step.
Days four to six: reading the logs like a detective 🔎
Once the dust settled, the job changed from “make it work” to “keep watching it”. For a couple of days the routine was simple: read nextcloud.log, the container logs and the ingress log, and for every line that looked odd ask why until there’s an answer. One precondition made that possible at all: the log level had been raised from 4 (fatal only) to 2 (warnings). At level 4, none of the following would have shown up. A quiet log isn’t always a healthy server. Sometimes it’s just a muted one.
Gremlin #4: the jail that watched a dead file
fail2ban was running, the nginx jails were “active”, and the ban list was empty. For days. Quiet week, or broken jail? The ingress controller writes its access log to a file whose name ends in a counter (…/0.log, 1.log, …), and every container restart starts a new one. fail2ban expands the logpath glob only when the jail starts. After a reboot fail2ban comes up before the ingress container, locks onto the old file, and then faithfully tails a log that nobody writes to anymore, on both hosts. The fix is a small systemd timer that notices when the set of ingress log files changes (and once after every boot) and reloads just the nginx jails. A security tool that reports “all quiet” because it’s looking at the wrong file is worse than none, because you think you’re covered.
Gremlin #5: the ownership ping-pong
Every playbook run, Nextcloud’s status.php briefly errored and the data directory failed its own writability check, then healed itself later in the same run. The culprit was two roles that disagreed. The SELinux role created the hostPath directories as root:root, and the deploy role set them to 33:33 (www-data). Each run flipped the ownership back and forth, and until the next role put it back, Nextcloud faced a data directory it wasn’t allowed to write. Now both roles set the same owner and mode, and the ping-pong is over. Two roles each doing something “correct” can still add up to a bug.
Gremlin #6: Office previews and the 1 MB wall
Small Word and Excel files got nice thumbnails in the file list, bigger ones didn’t. No error in the UI, just the generic icon. The ingress log had the answer: 413 Request Entity Too Large on every convert-to call to Collabora. Nextcloud renders Office previews by uploading the document to Collabora, and nginx’s default request body limit is 1 MB. The Nextcloud route had a generous limit, but the Collabora route never got one. One annotation (client-max-body-size: 2g) fixed it, and the affected previews can simply be regenerated. The few remaining convert-to errors are documents Collabora genuinely can’t open, which is a file problem and not a config problem.
Gremlin #7: the 108-megapixel photo
Some photos stayed thumbnail-less, and the app kept getting a 404 for their previews. All of them came from one phone, with 108 megapixels and 12,032 pixels across. Decoding an image that size takes around 430 MB of RAM, and Nextcloud’s preview_max_memory defaults to 256 MB. Above that, Nextcloud doesn’t even try. It silently skips the preview. Raised to 512 (PHP’s own limit is far above that), and the photos finally got their thumbnails.
While at it, iPhone HEIC photos got previews too. That’s one line in enabledPreviewProviders, with a catch: setting that key replaces the built-in default list instead of extending it, so the defaults (PNG, JPEG, GIF, text, OpenDocument…) have to be repeated, or you end up with HEIC previews and no JPEG ones. What’s left without a preview now is data, not configuration: a few dozen 400-byte leftovers from a years-old failed upload, some empty files, and a handful of PNGs larger than 50 MB.
Gremlin #8: the config that never arrived
Verifying the previous fix after a playbook run turned up something worse. The new values were in the Kubernetes ConfigMap, but the custom.config.php inside the running pod was a day old. The file is mounted with subPath, and a subPath mount is copied once at container start and never updated. Kubernetes updates normal ConfigMap volumes live, but not subPath ones. So every config change in the repo only took effect at the next accidental pod restart. (The preview fix worked in the meantime only because it had also been set via occ.)
The standard fix is a checksum/config annotation on the pod template: a SHA-256 of the rendered config templates. Change the config and the hash changes, which makes Kubernetes roll the pod. Leave the config alone and nothing happens. The blog got the same treatment for its nginx and PHP configs. Lesson: “the playbook ran green” and “the setting is active” are two different claims, so check the file inside the container.
What a healthy log looks like 🩺
After all that, the daily review has become boring, and that’s the goal. A typical day now has a handful of lines in nextcloud.log: a preview that couldn’t be opened, a PHP notice. The rest is noise worth knowing by heart, so it doesn’t send you hunting every morning:
- Collabora “Broken pipe” / “Connection reset”, around 60 an hour, even at 3 a.m.: the other side closed the connection before Collabora finished writing. Harmless.
- nginx “access forbidden” on
/data/.ncdataand/.env: the first is Nextcloud’s own security check verifying that the data directory isn’t reachable from the web, the second is a bot. Both blocked on purpose. - “config differs from the latest version of this image” on every pod start: the role manages those files itself (Redis with a password, for example), so they’re supposed to differ.
- notify_push “Self test failed” right after a reboot: the TLS check fails once with a certificate error (most likely the ingress still serving its default certificate for a few seconds before the real one is loaded). A minute later the self-test is 6/6 green.
The point of that list isn’t the entries themselves. Once you know what harmless looks like, the one line that isn’t harmless stands out immediately. That’s the whole trick of log monitoring. It’s not magic, it’s knowing the baseline.
Verdict ✅
It’s live. Certificates valid, Office editing works, data intact, users none the wiser. The migration itself was the easy 20%; the other 80% was a scavenger hunt for settings and behaviors that only misbehave under exactly the new conditions. As always: the server was never the problem — the assumptions were. 😄
Day three added a footnote to that. The nastiest bugs weren’t the ones that crashed — they were the ones that stayed green: a checkbox, a failure-tolerant playbook, an alert rule that couldn’t fire. If this migration taught me one habit, it’s to check the thing itself, not the thing that reports on it. 🔍
One more thing: this wasn’t my only Nextcloud rodeo. I also run a second production instance on a volunteer basis — smaller, with less data and fewer registered users — and everything I learned here turned out to be genuinely useful. So that one’s next: I’ll be migrating it onto the same K3s stack within the next two weeks, hopefully stepping on far fewer of these landmines the second time around. 🤞
The full Ansible stack behind all of this — the WordPress and Nextcloud roles, the ingress, cert-manager, the monitoring, and every hardening trick mentioned above — lives on GitHub, with secrets and host specifics stripped out: github.com/aptupgrademe/www_k3s. This migration is the v3.0.0 milestone, so you can browse the exact state described in this post rather than whatever HEAD happens to be today.
📚 More in this series: Nextcloud from bare metal to K3s